
Pricing
Pricing information has not been added yet.
Overview
PageIndex is an open-source reasoning-based RAG framework that retrieves information from long documents without relying on a vector database or conventional fixed-size chunking. It builds a hierarchical tree representation similar to an LLM-oriented table of contents and lets models reason over that structure to locate relevant sections.
The project is based on the idea that semantic similarity is not the same as relevance, especially in professional documents where questions may require contextual understanding and multi-step reasoning. Retrieval is performed through tree search, producing explicit section and page references that make results easier to trace and explain. A file-system layer extends the approach from individual documents to large collections.
PageIndex is aimed at document-analysis tasks involving financial reports, legal documents, regulatory filings, technical manuals, medical literature, academic material, and other long structured texts. It can be self-hosted and also has hosted, API, MCP, and enterprise deployment options, making it useful for teams exploring alternatives to embedding-heavy vector RAG.
README
PageIndex: Vectorless, Reasoning-based RAG
Reasoning-based RAG ◦ No Vector DB, No Chunking ◦ Context-Aware Retrieval ◦ Reads Like a Human
🌐 Website • 🖥️ Chat Platform • 🔌 MCP & API • 📖 Docs • 💬 Discord • ✉️ Contact
📢 Updates
- 🔥 Agentic Vectorless RAG — A simple agentic, vectorless RAG example with self-hosted PageIndex, using OpenAI Agents SDK.
- Scale PageIndex to Millions of Documents — PageIndex File System is a file-level tree indexing layer that lets PageIndex reason over an entire corpus, not just a single document, enabling massive-scale document search.
- PageIndex Chat — Human-like document analysis agent platform for professional long documents. Also available via MCP or API.
- PageIndex Framework — Deep dive into PageIndex: an agentic, in-context tree index that enables LLMs to perform reasoning-based, context-aware retrieval over long documents.
📑 Introduction to PageIndex
Are you frustrated with vector database retrieval accuracy for long professional documents? Traditional vector-based RAG relies on semantic similarity rather than true relevance. But similarity ≠ relevance — what we truly need in retrieval is relevance, and that requires reasoning. When working with professional documents that demand contextual understanding, domain expertise, and multi-step reasoning, similarity search often falls short — missing what's relevant but not similar, and returning what's similar yet not relevant.
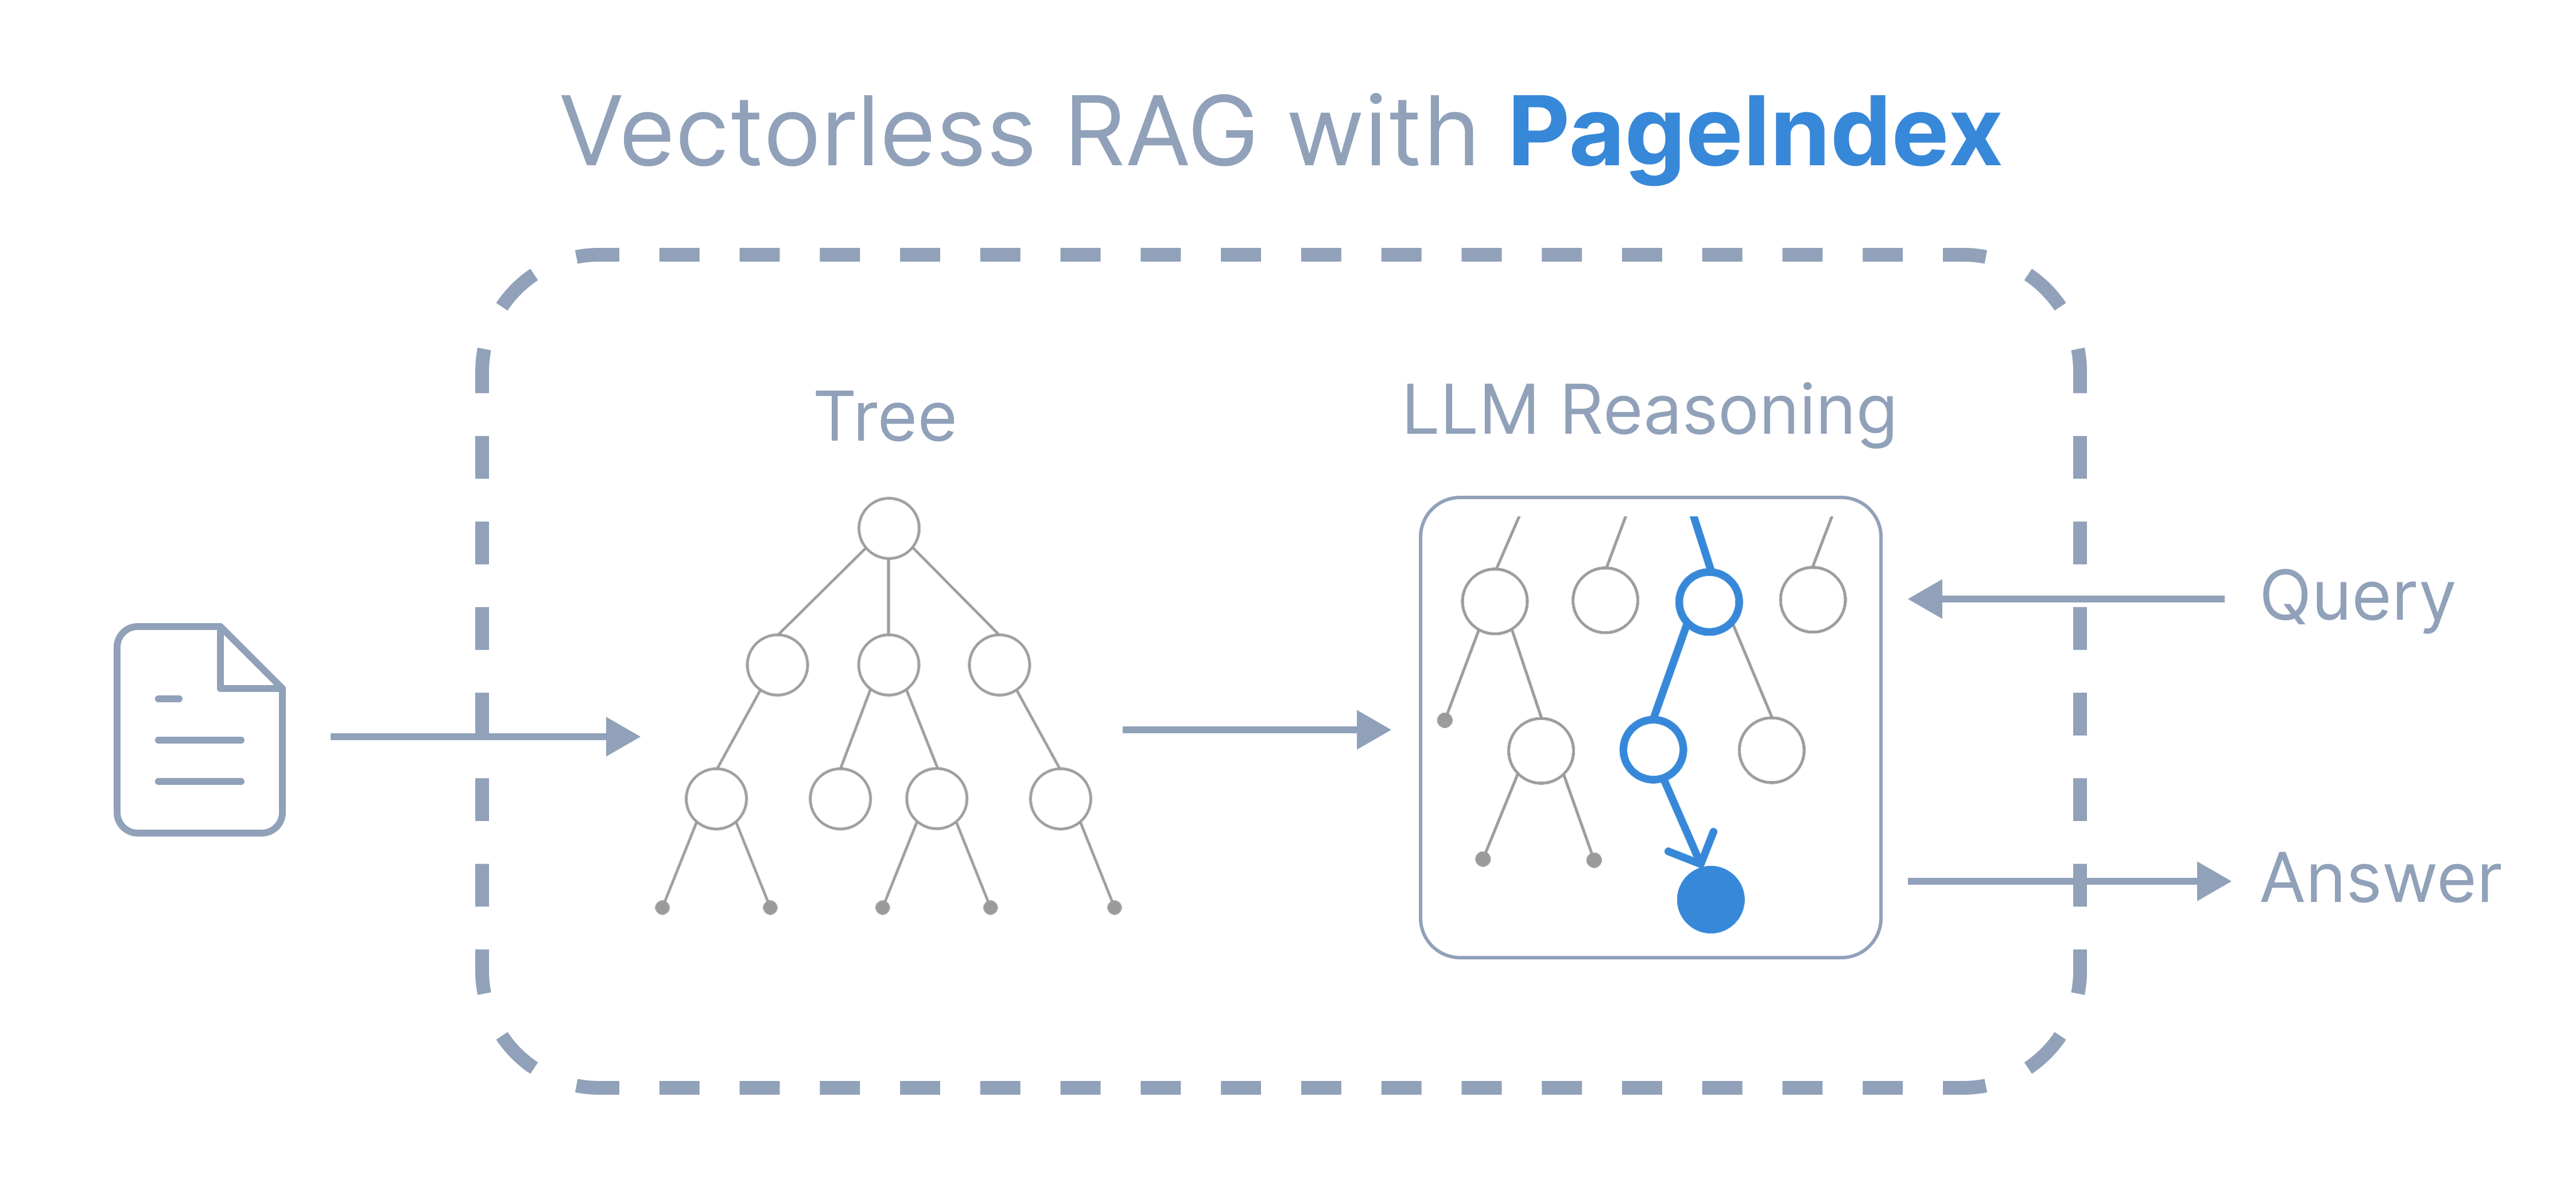
Inspired by AlphaGo, we propose PageIndex — a vectorless, reasoning-based RAG system that builds a hierarchical tree index from long documents, and uses LLMs to reason over that index for agentic, context-aware retrieval. The retrieval is traceable and explainable, with no vector DBs or chunking. PageIndex simulates how human experts navigate and extract knowledge from complex documents through tree search, enabling LLMs to think and reason their way to the most relevant document sections. It performs retrieval in two steps:
- Generate a “Table-of-Contents” tree structure index of documents
- Perform (agentic) reasoning-based retrieval through tree search
🎯 Core Features
PageIndex is a vectorless, reasoning-based RAG engine that mirrors how humans read, delivering traceable, explainable, and context-aware retrieval, without vector databases or chunking.
Compared to traditional vector-based RAG, PageIndex features:
- No Vector DB: Uses document structure and LLM reasoning for retrieval, instead of vector similarity search.
- No Chunking: Documents are organized into natural sections, not artificial chunks.
- Better Traceability & Explainability: Retrieval is reasoning-driven and grounded in explicit page and section references, making every result traceable and interpretable — no more “vibe retrieval” with opaque, approximate vector search.
- Context-Aware Retrieval: Retrieval depends on your full context (e.g., conversation history and domain knowledge), and easily incorporates new context.
- Human-like Retrieval: Mirrors how human experts navigate and extract knowledge from complex documents.
PageIndex achieved state-of-the-art 98.7% accuracy on FinanceBench (financial document QA benchmark), vastly outperforming vector RAG solutions on professional document analysis (blog post).
📍 Explore PageIndex
To learn more, please see a detailed introduction to the PageIndex framework. Check out our GitHub for open-source code, and the cookbooks, tutorials, and blog for more usage guides and examples.
The PageIndex service is available as a ChatGPT-style chat platform, or can be integrated via MCP or API, with enterprise deployment available.
🛠️ Deployment Options
- Self-host — run locally with this open-source repo (using standard PDF parsing).
- Cloud Service — production-grade pipeline with enhanced OCR, tree building, and retrieval for best results. Try instantly on our Chat Platform, or integrate via MCP or API.
- Enterprise — dedicated or private deployment (VPC, on-prem). Contact us or book a demo to learn more.
🧪 Quick Hands-on
- ⚡ PageIndex Flash (preview) — ultra fast PageIndex tree structure generation from PDFs.
- 🔥 Agentic Vectorless RAG (latest) — a simple but complete agentic vectorless RAG example with self-hosted PageIndex, using OpenAI Agents SDK.
- Try the Vectorless RAG notebook — a minimal, hands-on example of reasoning-based RAG using PageIndex.
- Check out Vision-based Vectorless RAG — no OCR; a minimal, vision-based & reasoning-native RAG pipeline that works directly over page images.


🌲 PageIndex Tree Structure
PageIndex can transform lengthy PDF documents into a semantic tree structure, similar to a “table of contents” but optimized for use with LLMs and AI agents. It's ideal for: financial reports, legal documents, regulatory filings, technical manuals, medical literature, academic textbooks, and any long, complex professional documents.
Below is an example PageIndex tree structure. Also see more example documents and generated tree structures.
...
{
  "title": "Financial Stability",
  "node_id": "0006",
  "start_index": 21,
  "end_index": 22,
  "summary": "The Federal Reserve ...",
  "nodes": [
    {
      "title": "Monitoring Financial Vulnerabilities",
      "node_id": "0007",
      "start_index": 22,
      "end_index": 28,
      "summary": "The Federal Reserve's monitoring ..."
    },
    {
      "title": "Domestic and International Cooperation and Coordination",
      "node_id": "0008",
      "start_index": 28,
      "end_index": 31,
      "summary": "In 2023, the Federal Reserve collaborated ..."
    }
  ]
}
...
You can generate PageIndex tree structures with this open-source repo. Or use our API for higher-quality results powered by our enhanced OCR and tree building pipeline.
⚙️ Package Usage
Note: This package uses standard PDF parsing. For use cases with complex PDFs, our cloud service (via MCP and API) offers enhanced OCR, tree building, and retrieval.
You can follow these steps to generate a PageIndex tree from a PDF document.
1. Install dependencies
pip3 install --upgrade -r requirements.txt
2. Set your LLM API key
Create a .env file in the root directory with your LLM API key. Multi-LLM is supported via LiteLLM:
OPENAI_API_KEY=your_openai_key_here
3. Generate PageIndex structure for your PDF
python3 run_pageindex.py --pdf_path /path/to/your/document.pdf
Optional parameters
You can customize the processing with additional optional arguments:
--model                 LLM model to use (default: gpt-4o-2024-11-20)
--toc-check-pages       Pages to check for table of contents (default: 20)
--max-pages-per-node    Max pages per node (default: 10)
--max-tokens-per-node   Max tokens per node (default: 20000)
--if-add-node-id        Add node ID (yes/no, default: yes)
--if-add-node-summary   Add node summary (yes/no, default: yes)
--if-add-doc-description Add doc description (yes/no, default: yes)
Markdown support
We also provide markdown support for PageIndex. You can use the `--md_path` flag to generate a tree structure for a markdown file.
python3 run_pageindex.py --md_path /path/to/your/document.md
Note: in this mode, we use "#" to determine node headings and their levels. For example, "##" is level 2, "###" is level 3, etc. Make sure your markdown file is formatted correctly. If your Markdown file was converted from a PDF or HTML, we don't recommend using this mode, since most existing conversion tools cannot preserve the original hierarchy. Instead, use our PageIndex OCR, which is designed to preserve it, to convert the PDF to a markdown file and then use this mode.
⚡ PageIndex Flash (preview)
PageIndex Flash (
pageindex/flash) generates tree structures from PDFs in seconds. Structure extraction is purely heuristic-based, no LLM needed. LLM is only used to generate node summaries.python3 run_pageindex.py --flash --pdf_path /path/to/your/document.pdfAdd
--optimizeto refine the tree structure for more efficient retrieval (with an LLM expansion pass).
🚀 Agentic Vectorless RAG: An Example
For a simple, end-to-end agentic vectorless RAG example using self-hosted PageIndex (with OpenAI Agents SDK), see examples/agentic_vectorless_rag_demo.py.
# Install optional dependency
pip3 install openai-agents

# Run the demo
python3 examples/agentic_vectorless_rag_demo.py
📈 Case Study: PageIndex Leads Finance QA Benchmark
Mafin 2.5 is a reasoning-based RAG system for financial document analysis, powered by PageIndex. It achieved a state-of-the-art 98.7% accuracy on FinanceBench (financial document QA benchmark), significantly outperforming traditional vector-based RAG systems.
PageIndex's hierarchical indexing and reasoning-driven retrieval enable precise navigation and extraction of relevant context from complex financial reports, such as SEC filings and earnings disclosures.
Explore the full benchmark results and our blog post for detailed comparisons and performance metrics.
🧭 Resources
- 📝 Blog: technical articles, research insights, and product updates.
- 🔧 Developer: MCP setup, API docs, and integration guides.
- 🧪 Cookbooks: hands-on, runnable examples and advanced use cases.
- 📖 Tutorials: practical guides and strategies, including Document Search and Tree Search.
⭐ Support Us
Leave us a star 🌟 if you like our project. Thank you!
Please cite this work as:
Mingtian Zhang, Yu Tang and PageIndex Team,
"PageIndex: Next-Generation Vectorless, Reasoning-based RAG",
PageIndex Blog, Sep 2025.
Or use the BibTeX citation.
@article{zhang2025pageindex,
  author = {Mingtian Zhang and Yu Tang and PageIndex Team},
  title = {PageIndex: Next-Generation Vectorless, Reasoning-based RAG},
  journal = {PageIndex Blog},
  year = {2025},
  month = {September},
  note = {https://pageindex.ai/blog/pageindex-intro},
}
🌐 Open-Source Ecosystem
PageIndex anchors a growing open-source ecosystem of long-context AI infra — OpenKB is an LLM knowledge base that compiles documents into an interlinked wiki. ChatIndex provides tree indexing and retrieval for long conversational histories and memory. ConDB is a KV-cache native context database for tree-based retrieval at scale. PageIndex MCP is PageIndex's MCP server.
Connect with Us



© 2026 Vectify AI
Releases
Release information has not been added yet.
Related articles
Guides and news that mention this tool.

AI Agents in Zapier vs Make vs n8n: Which Is Best?
What Is n8n? The Open-Source Workflow Automation Tool Explained
AI Email Labeling in Gmail with OpenAI
AI WhatsApp Customer Support Agent

Build a RAG Chatbot over Your Google Drive Documents

Build an AI Assistant on Telegram (Voice + Text) with n8n
Complete your AI stack
Add a general assistant, research, coding, monitoring, and team productivity to your automations.


Best alternatives
Compare similar tools in the same category.



